Enterprises
Many sites or business units, 3 or more vendors, change control and audit: one standard of evidence across all of them.
REAP for enterprisesAgentic AI for network operations
REAP is the agentic AI platform for network operations: the reasoning and assurance layer above the tools you already run. Incidents explained with evidence, changes checked before and after they land, and redundancy proven rather than assumed.
What changed
CHG-1234 edited object group OG-ERP on plant-a-core-2 at 21:14: members replaced (10.20.5.0/24 → 10.20.50.0/24) so a second ACL could reuse it. ACL-ERP-IN already referenced the group.
Why it broke
ACL-ERP-IN permits ERP return traffic by matching OG-ERP. With the members replaced, that traffic falls to the final deny. Link and OSPF never changed, so nothing alarmed.
Impact
ERP return traffic to Plant A order entry dropped on core-2 since 21:16: 1 device, 2 subnets, 1 service path. Undetected for 4 h 51 min; no probe watched the ERP path.
Next best action
Restore OG-ERP to its 21:13 members (runbook RB-07, awaiting approval); re-test ERP reachability; re-implement CHG-1234 with a separate group; add a probe on the ERP path.
Evidence · each item one click from the conclusion
3 more items · fictional network · 4 independent sources agreeSee the full investigation
The reality of network operations
Incident Reasoning
Restored is not the same as fixed.
Accelerate root-cause analysis. (Incident Reasoning)Change Assurance
Completed is not the same as verified.
Validate change outcomes. (Change Assurance)Resilience Assurance · posture & compliance
Configured is not the same as compliant.
Uncover operational risks. (Resilience Assurance)Most network incidents are closed when service comes back, not when the cause is known. Most changes are marked successful because nobody complained. Most devices that match their intended configuration have never been checked against the policy they are supposed to enforce. All three leave the condition in the network. It comes back, usually in business hours, usually to a different first responder who starts from zero.
REAP closes the gaps with evidence: a root cause you can trace to the exact command output, log line or configuration diff; evidence on every change, before it runs and after it lands, recorded in the ticket; and posture findings an auditor can read. When something is beyond an agent’s certainty, REAP says so and proposes the next diagnostic step rather than guessing.
REAP in 90 seconds
0:00–0:08 21:14. A change goes in. Closed “successful.” CHG-1234 edits object group OG-ERP on plant-a-core-2. Closed at 21:20. No post-check.
0:08–0:16 21:16. The ERP path fails. Nothing alarms. ACL-ERP-IN matched OG-ERP. ERP return traffic now hits the final deny. Link and OSPF stay up.
0:16–0:24 02:07. P1. Plant A can’t enter orders. The night-shift help desk opens INC0451. Undetected for 4 h 51 min.
0:24–0:33 Every incident starts from zero. Six tools. Three teams. The answer is in there, spread across all of them. Engineers spend 37% of their time addressing disruptions.
0:33–0:42 REAP observes. Read-only. Config history, ACL counters, routing and the change ticket, gathered into one investigation.
0:42–0:52 It reasons with evidence, one step at a time. What changed, why it broke, what is affected. Each line traces to its source.
0:52–1:00 It recommends an approved runbook. A person decides. Restore OG-ERP to its 21:13 members with RB-07. Awaiting approval. Approval-gated runbooks: pilot deliverable today.
1:00–1:10 Before and after. A verdict, in the ticket. ERP path re-tested after RB-07: Verified. CHG-1234 recorded as Rolled back, with evidence. Before-and-after verification: pilot deliverable today · automated verdicts: in development.
1:10–1:18 Start through one door. Incident Reasoning. Change Assurance. Resilience Assurance. Expand only when you pull.
1:18–1:24 Restored ≠ Fixed. Completed is not the same as verified. Configured is not the same as compliant.
End card, 1:24–1:30 REAP · Observe · Reason · Act · Prove Network Assurance without Compromise™ Bring us your last P1 — reapnet.ai
Illustrative, on a fictional network. · Source: New Relic (opens in a new tab), 2026 Observability Forecast (opens in a new tab)
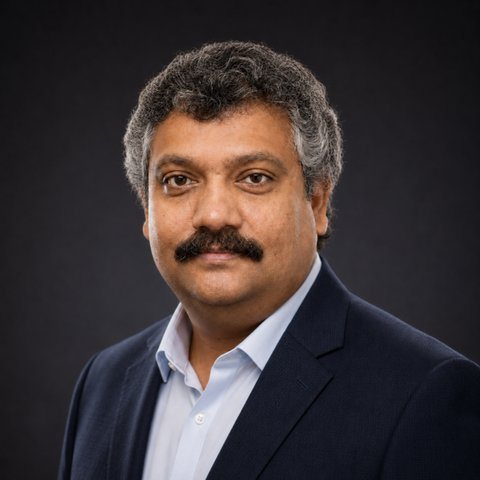
Raja Rao Tadimeti
Co-founder & CEO
Co-founded WiteSand (acquired by Juniper); founding engineer at Pensando and Insieme
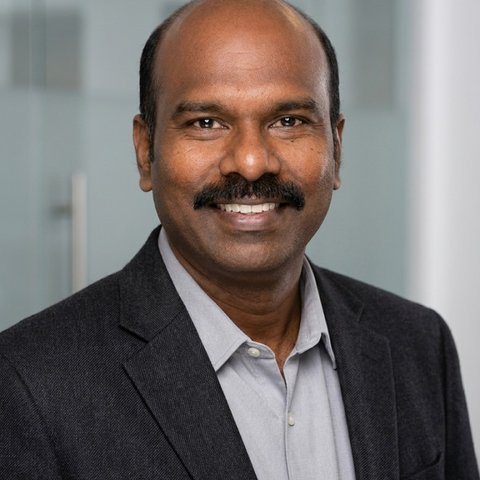
Natarajan “Nata” Manthiramoorthy
Co-founder · Customer Success & Solutions Engineering
Early engineer at WiteSand, Pensando, Innovium, Insieme, Aruba, and Andiamo
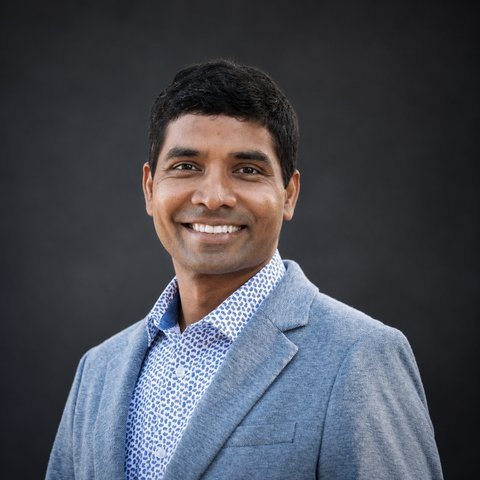
Madhava Cheethirala
Co-founder · VP of Engineering
Co-founded WiteSand; founding engineer at Pensando and Insieme; built networking products at Cisco, VMware and Juniper
What network leaders told us
Three problems too costly to leave open. A 45-day pilot starts with the one that hurts most.
Each business unit runs its own network, vendors and habits. A P1 in one company took a week to explain because the context lived in three teams’ heads. The leadership question: “Why does every incident start from zero?”
Firmware and OS upgrades were validated by ping and a checklist. A “successful” upgrade changed behavior that surfaced days later as user complaints. The ask: prove, before and after, that a change did only what it was meant to do.
A redundant firewall and VPN pair was “in sync” on paper. The standby had drifted, and the failover that was supposed to be invisible was not. The ask: prove that redundancy actually works, before it is needed.
Anonymized patterns from REAP design partners: no names, identifying details changed. Named references follow only when a customer has measured results and has agreed in writing.
The problem
Telemetry, configurations, tickets, topology, runbooks and vendor documentation live on separate islands, bridged today by expert people and hard-coded automation.
Half of major network outages trace to a configuration or change-management failure (Uptime Institute (opens in a new tab), Annual Outage Analysis (opens in a new tab) 2025), and 42% of organizations learn about a disruption from manual checks or customer complaints (New Relic (opens in a new tab), 2026).
Cost your last P1
Count the P2s too: the ones that never reach the board deck add up over a year. If your operations are customer-facing, a network incident is a customer outage; add the SLA credits and the churn.
Your last P1
—
A year of P1s and P2s
—
Your numbers, your math; nothing leaves this page. At the New Relic (opens in a new tab) mean, a two-hour P1 is $3.7M.
Three doors
Every engagement starts through one door and expands only when you pull. Automated change verdicts and continuous failover-readiness proof are In development, built with design partners.
Incident Reasoning
The P1 at 02:07 was a change that closed as successful at 21:20. REAP finds the change, the cause and the blast radius, with the evidence attached.
In a pilot todayreplayed incidents whose root cause you know and we do not, then live ones
Explain incidents with evidenceChange Assurance
Impact on redundancy, reachability and policy before the change runs; configuration and state compared after it lands; the evidence recorded in the change ticket.
In a pilot todayone real change window, verified with your team
Evidence on every changeResilience Assurance
Standby pairs out of sync, configuration drift and CVEs that apply to the features you run, each finding with evidence an auditor can read.
In a pilot todayfindings reviewed with your architect in week 3
Find where redundancy will not holdIs REAP built for your estate?
If two are true, REAP is built for your estate. Start with a 45-day proof of value on one domain
Who runs the loop
Built for multi-vendor estates, and for single-vendor estates made complex by AWS (opens in a new tab) or Azure (opens in a new tab) hybrid cloud, run by lean teams. How you start depends on who runs the network.
Many sites or business units, 3 or more vendors, change control and audit: one standard of evidence across all of them.
REAP for enterprises3 to 10 network engineers, many sites and no 24x7 NOC: incidents open with what changed and the evidence behind it.
REAP for mid-sized companiesMany customer estates from one console (Available; per-operator customer scoping is In development). Smaller businesses get REAP through the MSP that runs their network.
REAP for MSPsWhere REAP fitsManufacturing plantsHospitals and health systemsUniversitiesBanks and insurersRetail and distributionData centers and neocloudsMSPs
New to the category? Read What is network assurance? or follow a day with REAP, hour by hour.
Proof of Value
A pilot is not a demo. Ours starts with your baseline and ends with BUY, EXTEND or STOP in front of the person who signs.
Week 0
Baseline worksheet, success scorecard, security packet, week-0 data request.
Weeks 1–4
Connect and discover; replay 5–10 incidents whose root cause you know and we do not; findings review; one real change window compared before and after; runbooks under approval.
Week 5
Before and after on eight measures; the value model on your numbers.
Week 6
Business review: what REAP found that you did not know, what it did faster or better, what capacity or risk that is, and what production costs against the value.
Design targets from REAP’s reference architecture, not measured customer results. The 45-day proof of value measures eight things, not three, and replaces these with your numbers.
Works with what you already have
Read-only by default; credentials brokered through CyberArk (opens in a new tab) where available; evidence written back to your ticket.
Planned, not available today: HashiCorp Vault (opens in a new tab), SolarWinds (opens in a new tab), Zabbix (opens in a new tab), PagerDuty (opens in a new tab), Opsgenie (opens in a new tab), Confluence (opens in a new tab) and SharePoint (opens in a new tab); tell us which you need. NetBox (opens in a new tab) reconciliation on request. REAP collects its own telemetry today, and incidents your monitoring raises reach REAP through ServiceNow (opens in a new tab) or Jira (opens in a new tab).
Fortinet (opens in a new tab), SONiC (opens in a new tab) and other platforms: coverage confirmed per pilot against your platforms and versions.
Questions buyers ask first
REAP is an agentic AI platform for network operations: a reasoning and assurance layer that works above your monitoring, ITSM, PAM, on-call and network platforms. It observes your environment, reasons over live evidence and acts under your governance — read-only by default, approval-gated when it acts.
No. Nothing is replaced, including the AI assistants your network vendors and your ITSM ship. Use them: each knows its own devices or its own tickets well. REAP reasons across all of them — every vendor in the estate plus the tickets and configuration history between them — and writes its findings and evidence back into the tickets you already use. The test: an incident that crosses vendors, or follows a change made in another tool.
Not until you say so. REAP starts read-only and recommends with evidence; any write runs inside a runbook you approved, behind a confirmation, with role-based access and a full execution record. Autonomy expands only as you approve it, action type by action type.
REAP runs as SaaS on AWS (opens in a new tab) in U.S. regions today; deployment in your own cloud account or on-premises is available by arrangement. Customer data is not used to train models without your written consent. REAP collects configurations, command output, topology and telemetry through connectors in your network over an outbound TLS tunnel, and reads ticket data from your ITSM; device credentials are read-only, can be brokered from CyberArk (opens in a new tab) and can be revoked by you at any time. Retention, model-endpoint options and the rest are in the security packet, sent under NDA. See the Trust Center.
No. They are design targets from REAP’s reference architecture and are labeled as such. Every proof of value starts with your baseline and reports measured results against it.
By the size of the managed environment and the capability tier — never per engineer. A paid proof of value is credited in full against the first annual subscription when the order is signed within 30 days of the business review. See pricing.
Some teams should: if a platform team already builds and runs your own agents, build. For everyone else the demo is the cheap part; operating an agent safely for years is the product — collectors for every vendor, model evaluations, guardrails, integrations and a security review each time something changes. Buy the engine, own the edges: REAP runs the reasoning engine; you keep the topology knowledge, runbooks, change policy and approvals.
Then you can see why: every conclusion is shown with the commands, outputs and timestamps it rests on, so a wrong answer is visible instead of hidden in a confident sentence. REAP does not act on its own conclusions. In a pilot your senior engineers score every conclusion, including the wrong ones, and the score is reported at the business review.
A named person on your team, by design. REAP recommends; any change runs only inside a runbook your team approved, behind a confirmation, and REAP logs every runbook execution with the device output. Nothing changes on a device because a model concluded it should.
Not yet, and we will not pretend otherwise. REAP runs today with design partners who have not yet agreed to take reference calls. Instead we offer a walkthrough session on your own last P1, founders at your kickoff and business review, and a paid pilot that ends in BUY, EXTEND or STOP on a date you set.
Your network would not notice. REAP is not in the data path and holds no standing write access; the evidence it wrote into your tickets stays in your ITSM, and your data is deleted on request under the agreement.
Cisco (opens in a new tab), Arista (opens in a new tab), Juniper (opens in a new tab), HPE Aruba (opens in a new tab) and Palo Alto Networks (opens in a new tab) estates; AWS (opens in a new tab) and Azure (opens in a new tab) network constructs; Aruba Central (opens in a new tab), Juniper Mist (opens in a new tab) and Cisco Meraki (opens in a new tab); ServiceNow (opens in a new tab), Jira (opens in a new tab) and ManageEngine; Slack (opens in a new tab) and Microsoft Teams (opens in a new tab); CyberArk (opens in a new tab) credential brokering; SSO through Okta (opens in a new tab) and Microsoft Entra ID (opens in a new tab). Fortinet (opens in a new tab), SONiC (opens in a new tab) and other platforms: coverage confirmed per pilot. NetBox (opens in a new tab) reconciliation: on request. Planned, not available today: HashiCorp Vault (opens in a new tab), SolarWinds (opens in a new tab), Zabbix (opens in a new tab), PagerDuty (opens in a new tab), Opsgenie (opens in a new tab), Confluence (opens in a new tab) and SharePoint (opens in a new tab). See integrations.
Keep the root cause to yourself; in a 30-minute session we walk through how REAP would have investigated it, evidence first. The replay on your own network happens inside the proof of value. Or meet us at ONUG Fall 2026 (opens in a new tab) in New York, October 28–29.